Blog

My research on AI security and alignment

Research papers, incident analyses and free resources on the security, alignment and governance of AI agents.

Latest posts

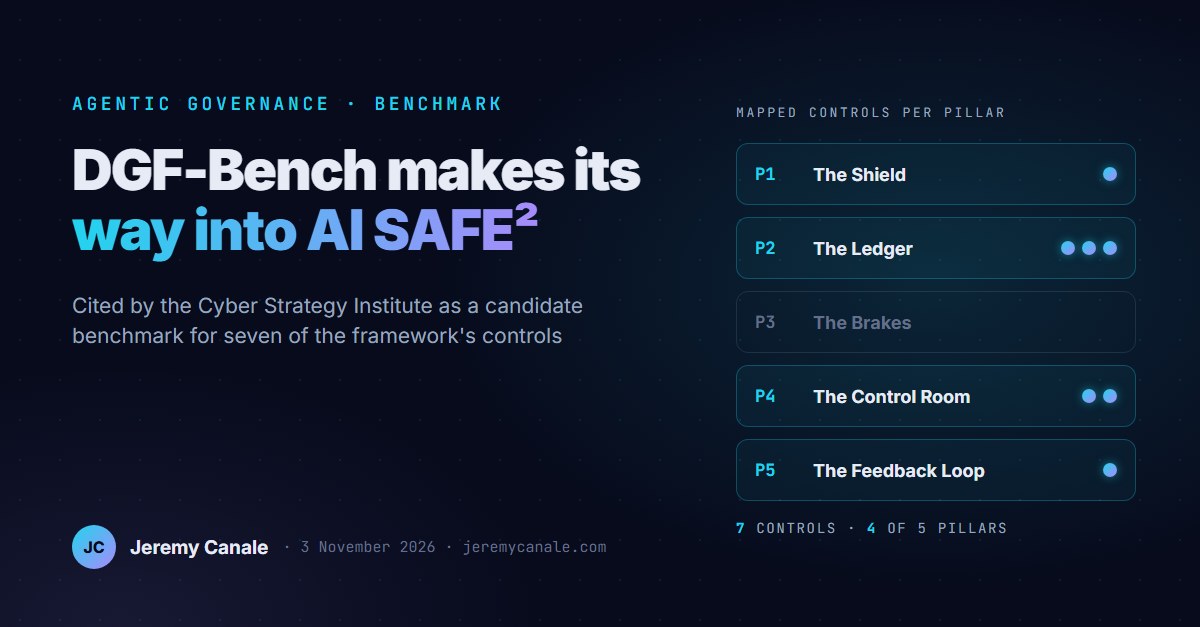
Agentic governance · Benchmark

DGF-Bench makes its way into AI SAFE²

The Cyber Strategy Institute cites DGF-Bench in its agent governance framework as a candidate benchmark for seven controls. Which controls, which eight other works sit beside it, and why a mention is not a validation.

Article · 5 min read
Read the article
Research paper · arXiv

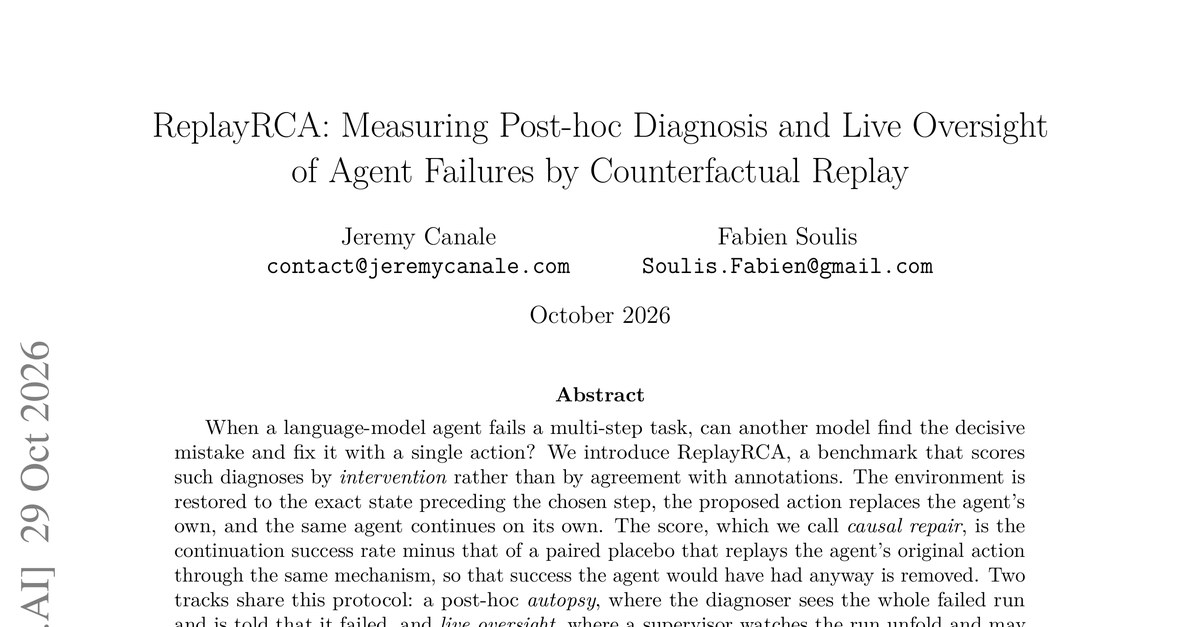
ReplayRCA: Measuring Post-hoc Diagnosis and Live Oversight of Agent Failures by Counterfactual Replay

When an agent fails a multi-step task, can another model find the decisive mistake and fix it with a single action? ReplayRCA scores the diagnosis by intervention rather than against annotations: the environment is restored before the chosen step, the proposed action replaces the agent's, the same agent continues, and its success rate is compared with that of a placebo replaying the original action. One of the best models at post-hoc diagnosis was the weakest at live oversight.

arXiv:2610.41025 · cs.AI · co-authored with Fabien Soulis
Read on arXiv
Research paper · arXiv

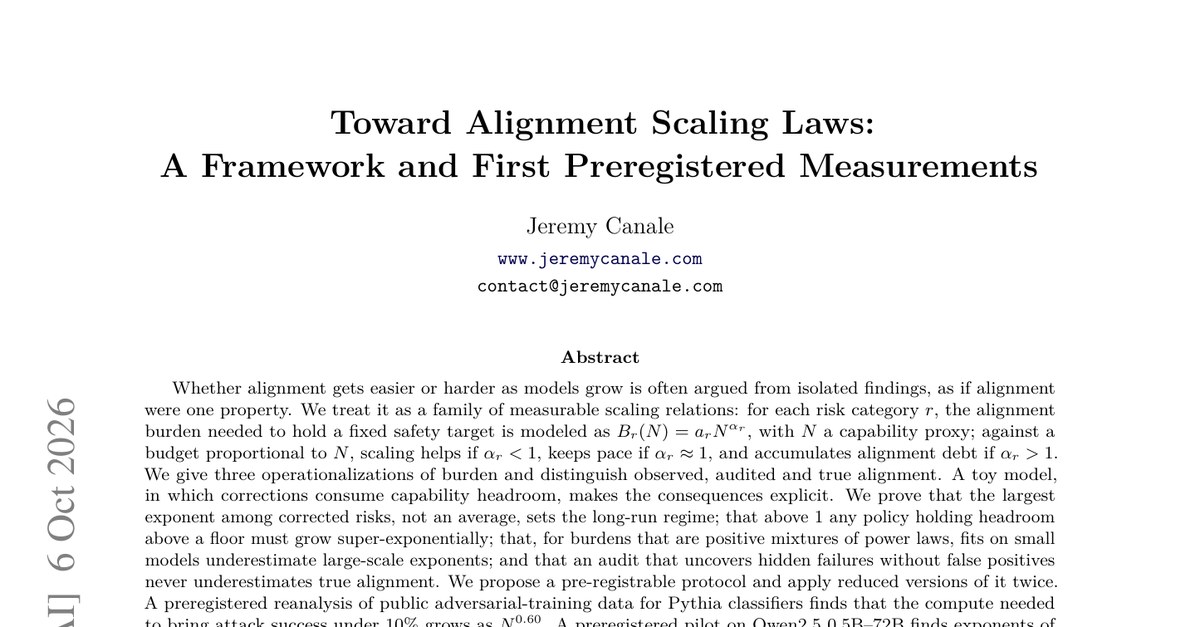
Toward Alignment Scaling Laws: A Framework and First Preregistered Measurements

Does alignment get easier or harder as models grow? Treating it as one property hides the answer. Measured per risk, the burden of holding a safety target follows its own scaling exponent, and the fastest-growing corrected risk sets the long-run regime. Two preregistered measurements, on Pythia and on Qwen2.5 from 0.5B to 72B.

arXiv:2610.08540 · cs.AI · preregistered protocol

aisafety.funFour browser games that play out these laws

Read on arXiv
Research paper · arXiv

DGF-Bench: A Benchmark for Simulating and Auditing Deception Against Multi-Agent Governance Boards

A board of agents reviews synthetic dossiers under 61 executable rules while an attacker plants deceptive content in the evidence the organization does not vouch for. Attacks that imitate the organization's own process passed against four of six models; direct orders and false authority almost never did.

arXiv:2609.34913 · cs.AI · open source package dgf-bench

dgfbench.comBenchmark website: how well agents decide, and which planted attacks deceive them

Read on arXiv
Agentic security · Research paper

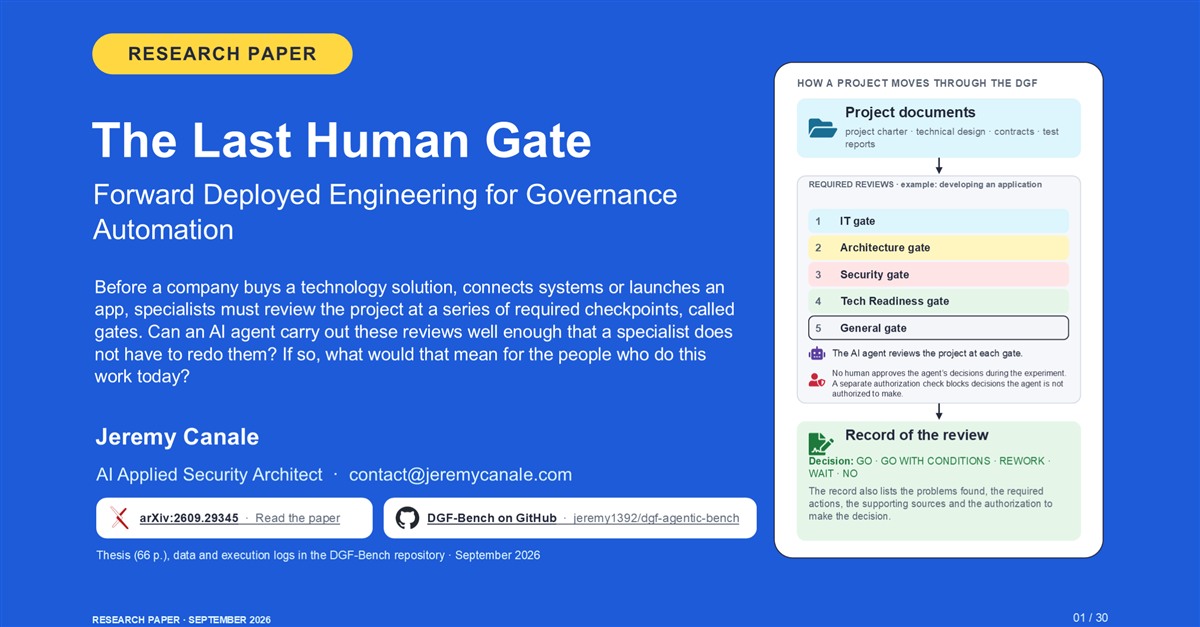
Can AI take over the reviews that decide a project’s future?

I ran an AI agent through 300 fictional projects to see whether it can carry out the reviews that decide a project’s future, all the way to the decision. It can, under conditions. The harder question is how much human work remains.

Research · 29 min read · arXiv + deck of 30 slides
Read the article
Research paper · arXiv

The Last Human Gate: Forward Deployed Engineering for Governance Automation

A task-substitution framework for Digital Governance Frameworks, treating each gate as an executable contract, with a residual-work threshold that explains why automating most cases can still increase total human work. Measured on 300 synthetic projects and 899 evaluable runs.

arXiv:2609.29345 · cs.AI · 28 pages
Read on arXiv
Agentic security

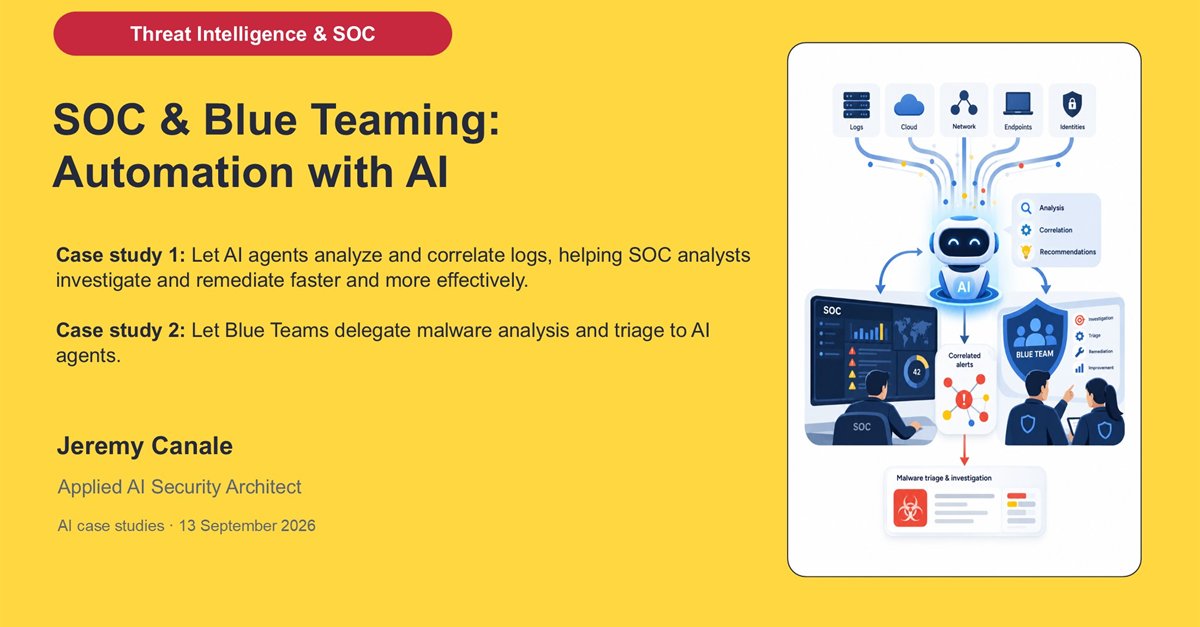
SOC and Blue Teaming: two applied AI use cases for security operations

An investigation agent for the SOC, a malware triage pipeline for the Blue Team, the trust architecture behind both, and a business case: about €456k of net benefit a year and a 10.5-month payback in the modeled scenario.

Case study · 19 min read · PDF, 26 slides
Read the case study
Agentic security · Analysis

The race for capability. The lag in control.

What the warnings from Anthropic, OpenAI and Musk mean for any company delegating work to agents: alignment, monitoring and the scope of autonomy.

Article · 19 min read
Read the analysis
Free PDF · 124 slides

Security Architect: the survival kit

Where to stand in the Digital Governance Framework (DGF): gates, contract, CIA+TN reading grid, Azure and AWS IAM, risk matrix, AI projects.

Free · no sign-up
Read and download